Human-validated training data | Pilot-to-scale delivery | Multimodal coverage

Josisoft Technologies

HomeData Collection IndustriesHow We WorkAboutCareers / Join as an AnnotatorContactGet in Touch
TEXT & NLP ANNOTATION

Structured Language Annotation for NLP and Generative AI Systems.

Text datasets become useful when language is consistently mapped to the concepts a model needs to learn. Entities, intents, relationships, spans, categories, attributes, and linguistic structure all require clear annotation rules and careful review. Josisoft builds text annotation workflows around your taxonomy, label definitions, edge cases, language requirements, and QA criteria so raw text becomes reliable structured ground truth.

Talk to a Data Specialist
LANGUAGE DATA OPERATIONS

Core Text & NLP Annotation Capabilities

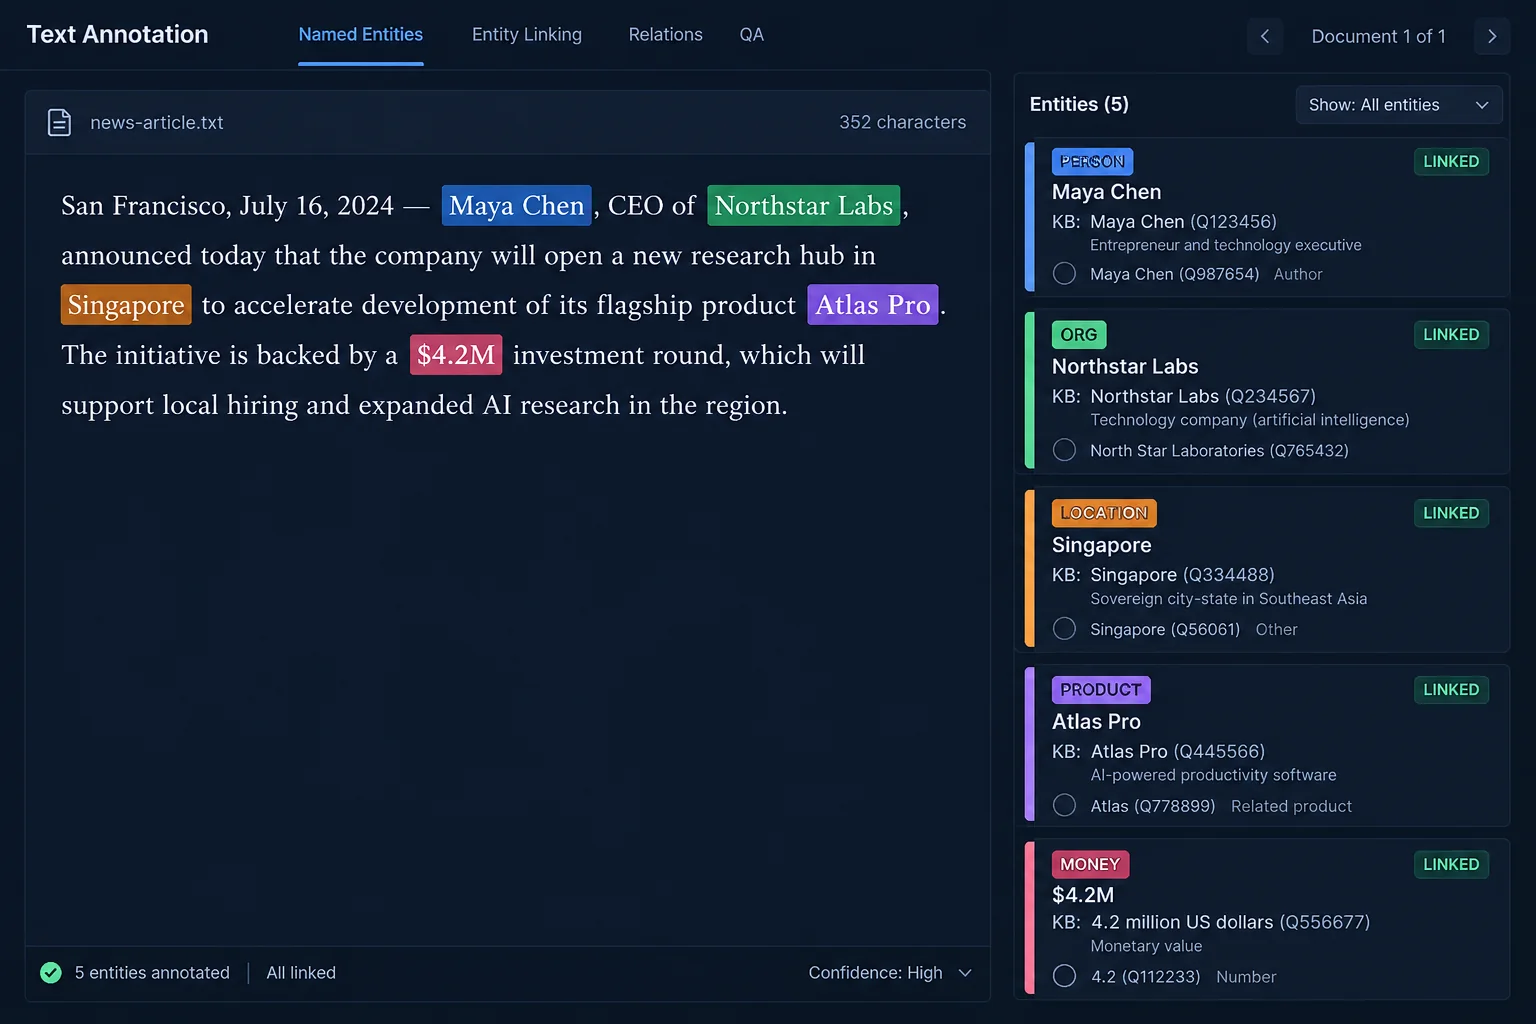
Named Entity Recognition (NER) & Entity Linking

Identification and span-level boundary annotation of standard and custom entities (persons, organizations, locations, products, numeric expressions), with grounding and disambiguation to external knowledge bases and client ontologies.

Relation Extraction (RE) & Knowledge Graph Triples

Semantic relation labeling between co-occurring entities within sentences or multi-paragraph texts, generating structured Subject-Predicate-Object triples for knowledge base construction and information extraction.

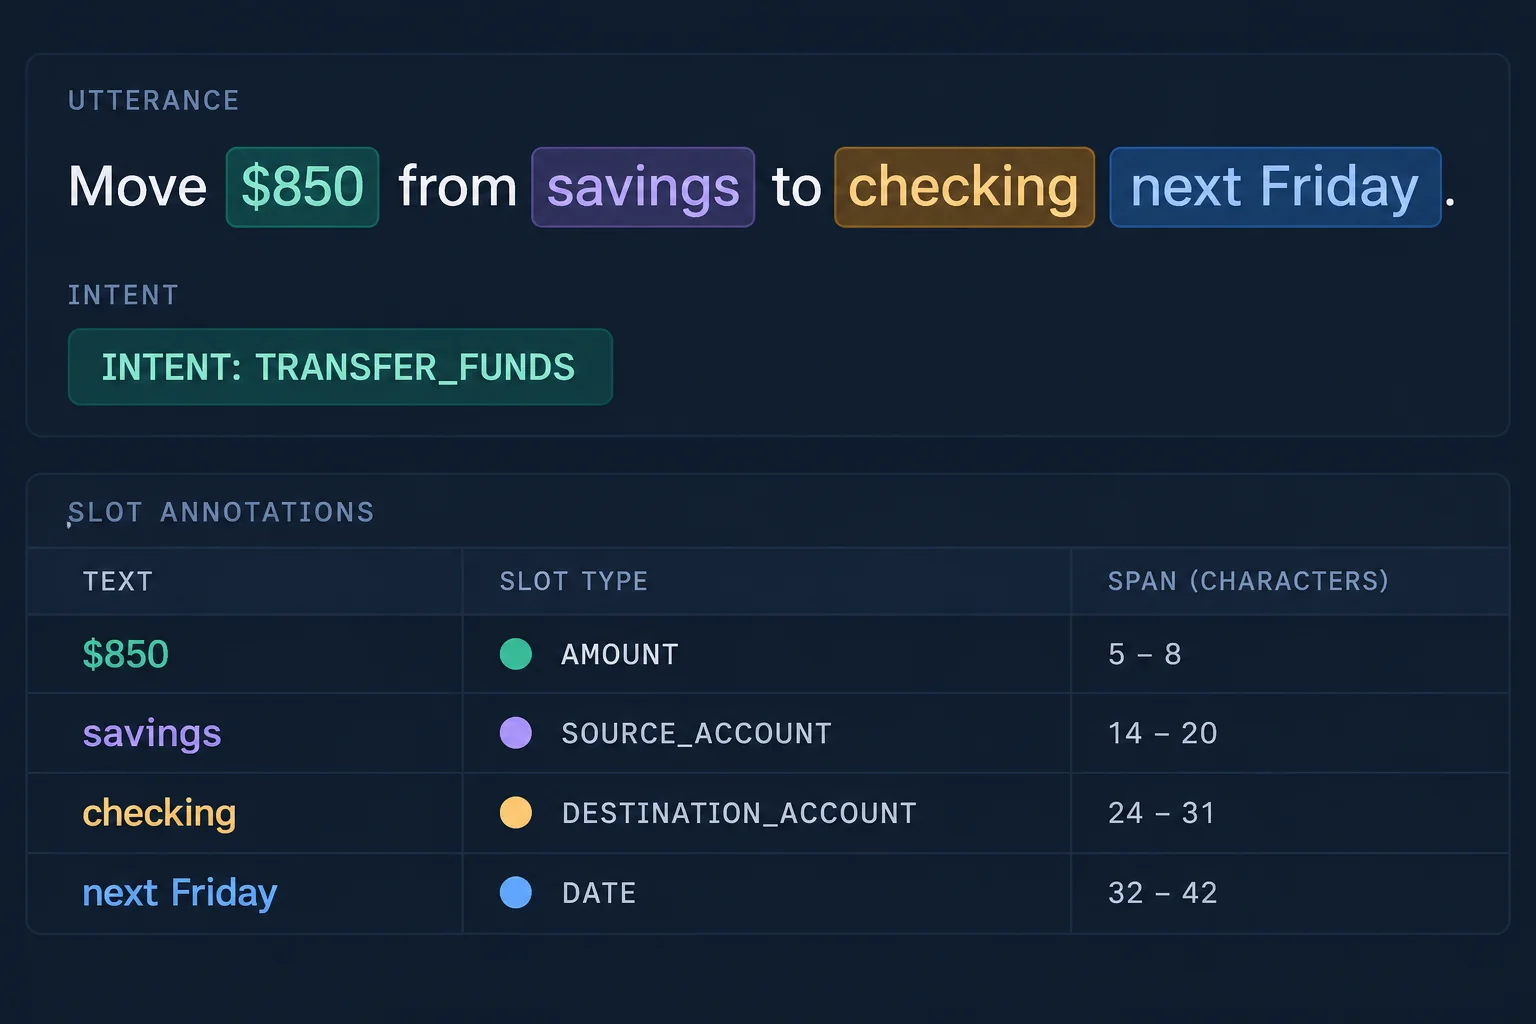
Intent Classification & Slot Filling (Conversational NLU)

Joint labeling of user utterances across dialogue flows, assigning top-level domain intents alongside fine-grained semantic slot entities for task-oriented chatbots, virtual assistants, and IVR systems.

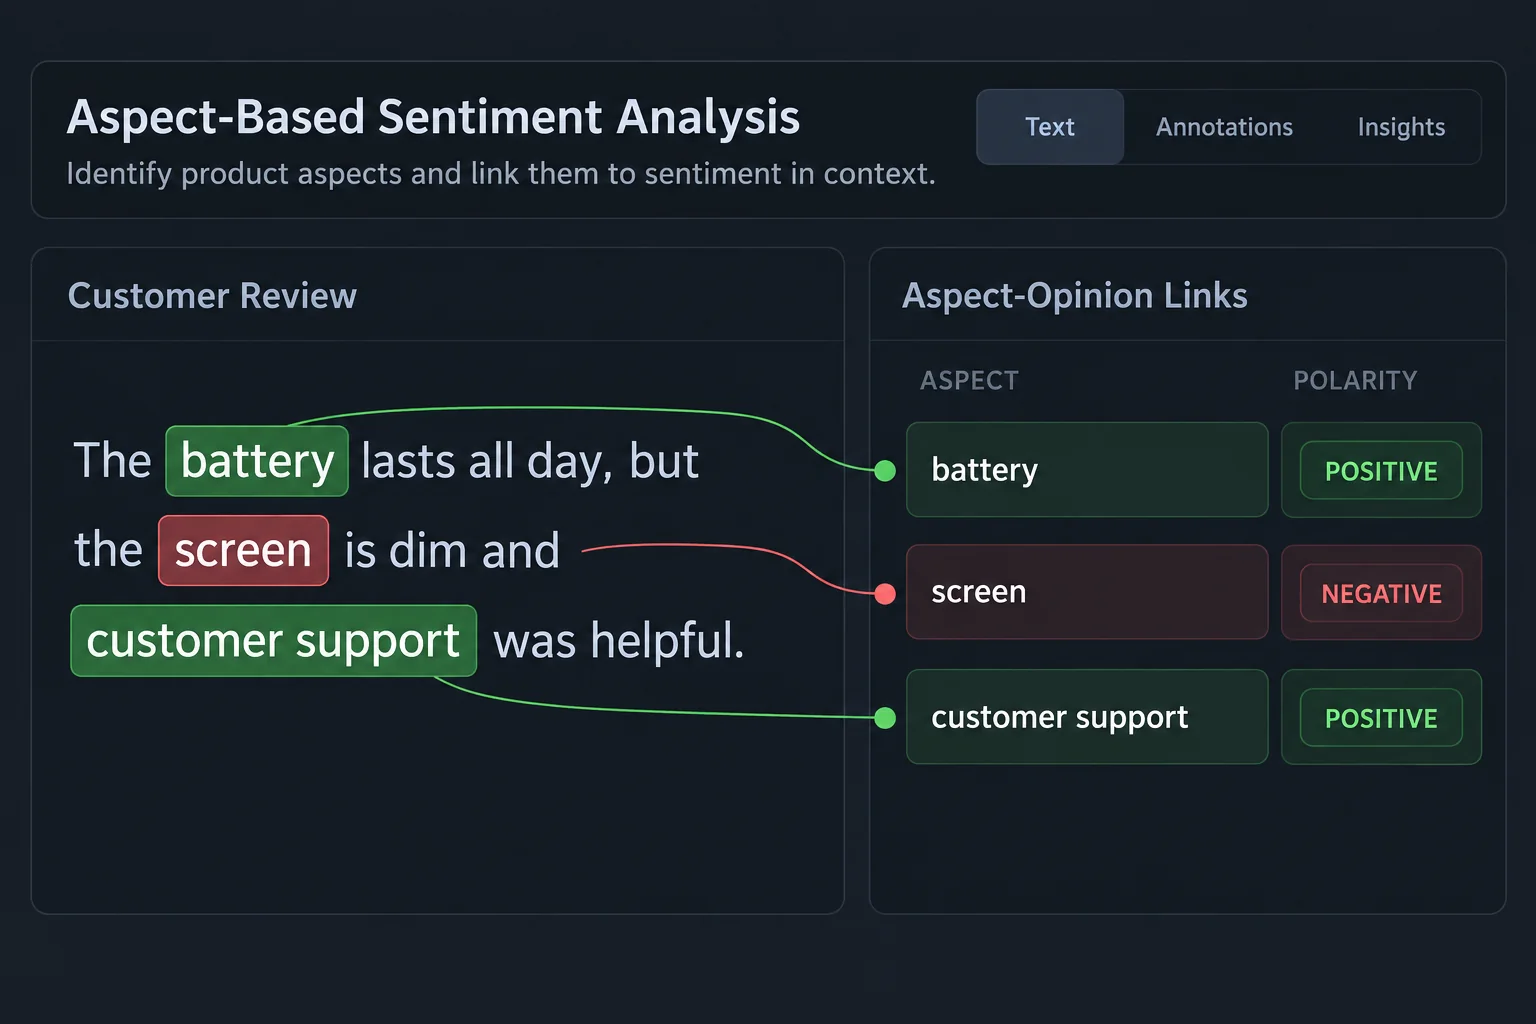
Aspect-Based Sentiment Analysis (ABSA) & Opinion Mining

Fine-grained sentiment tagging linking polarity values (positive, negative, neutral) directly to specific entity attributes, feature aspects, and contextual opinion targets within customer reviews and feedback.

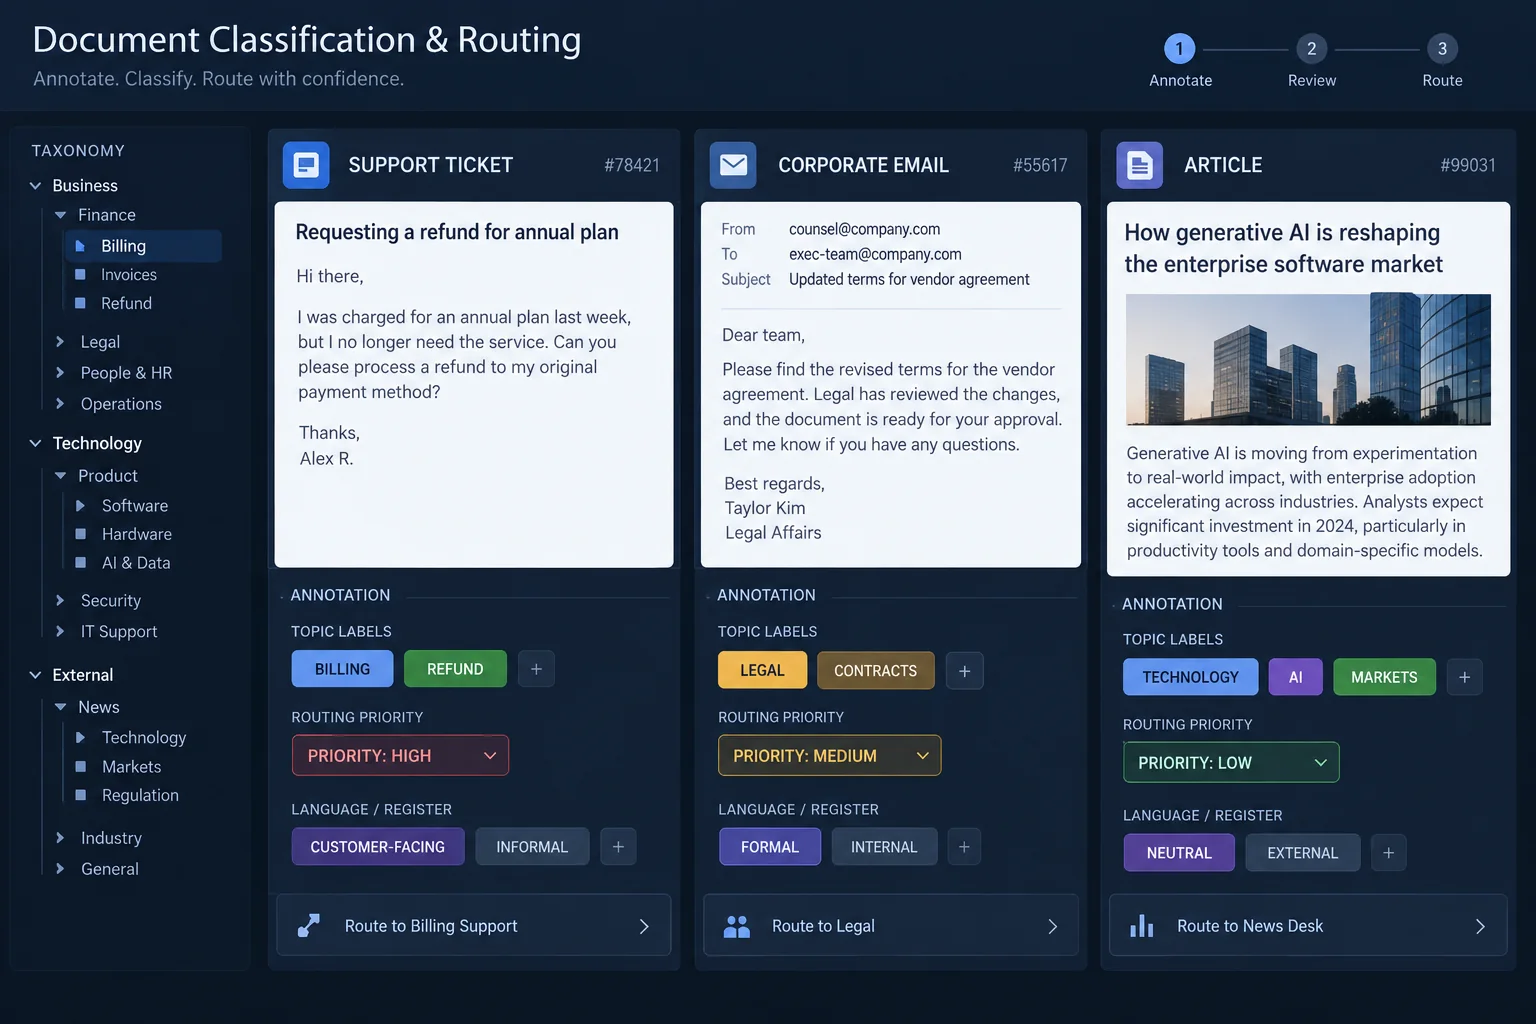
Document & Multi-Label Text Classification

Hierarchical, single-label, and multi-label document categorization tagging topic taxonomies, subject matter, routing priority, and language registers across support tickets, corporate emails, and articles.

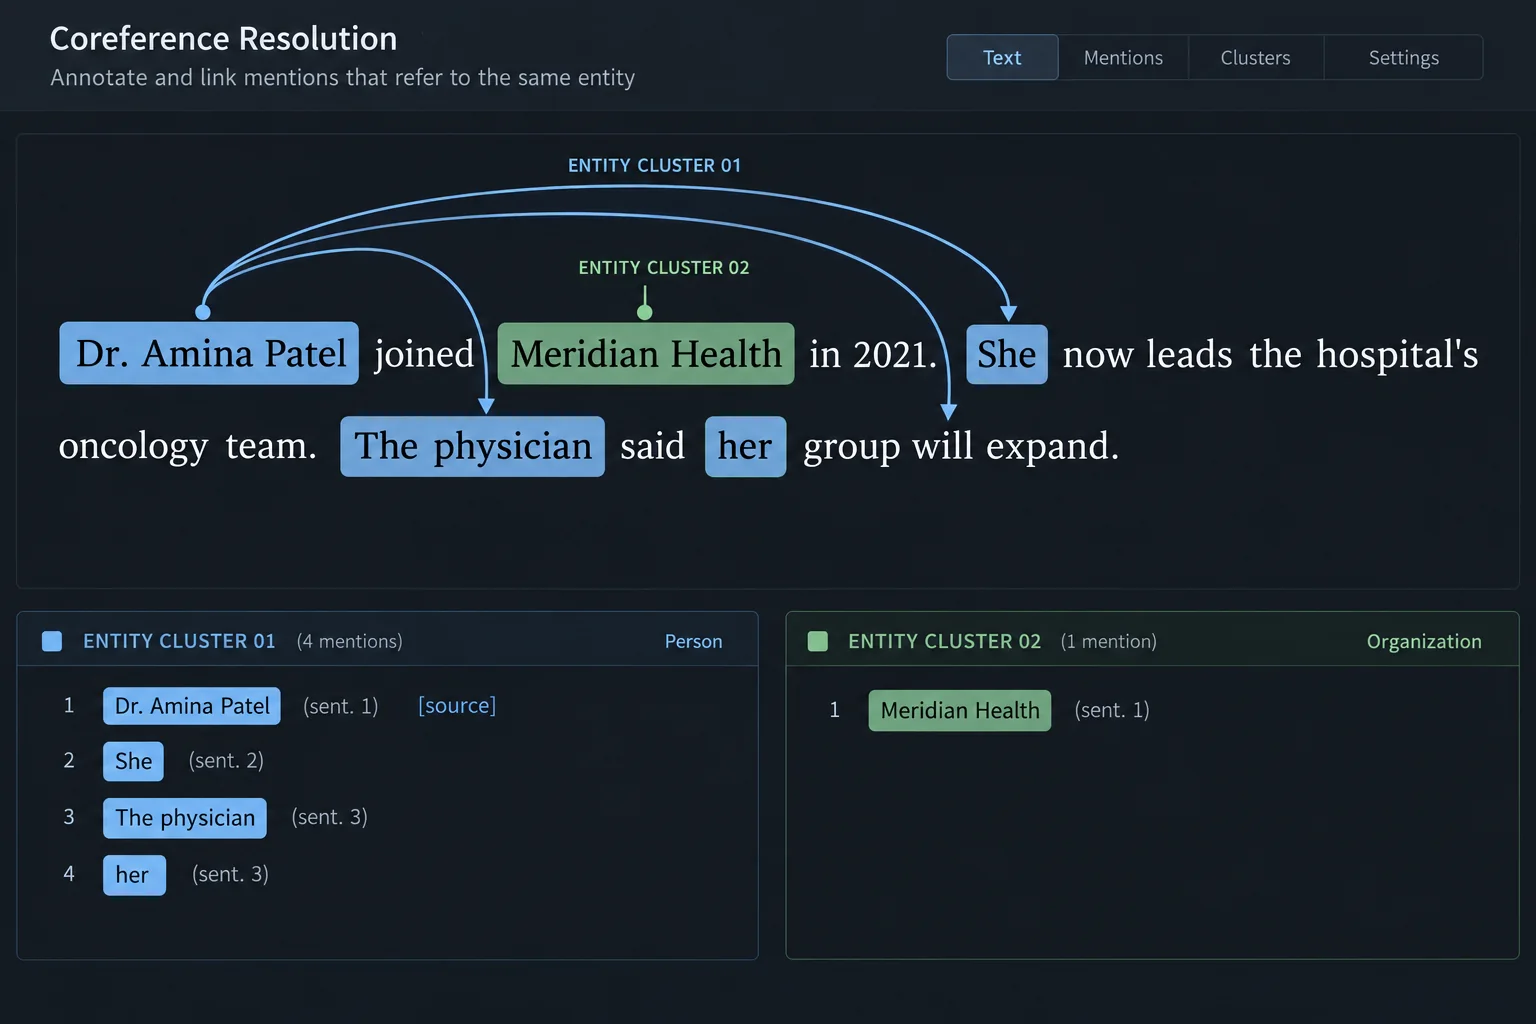
Coreference Resolution & Anaphora Linking

Directed clustering linking pronouns, noun phrases, aliases, and nominal mentions to their single shared referent entity across complex, multi-speaker, and multi-page texts.

Semantic Role Labeling (SRL) & Syntactic Parsing

Frame-based linguistic parsing mapping predicate-argument structures ("who did what to whom, when, where, and how") alongside Part-of-Speech (POS) tags and Universal Dependency syntax trees.

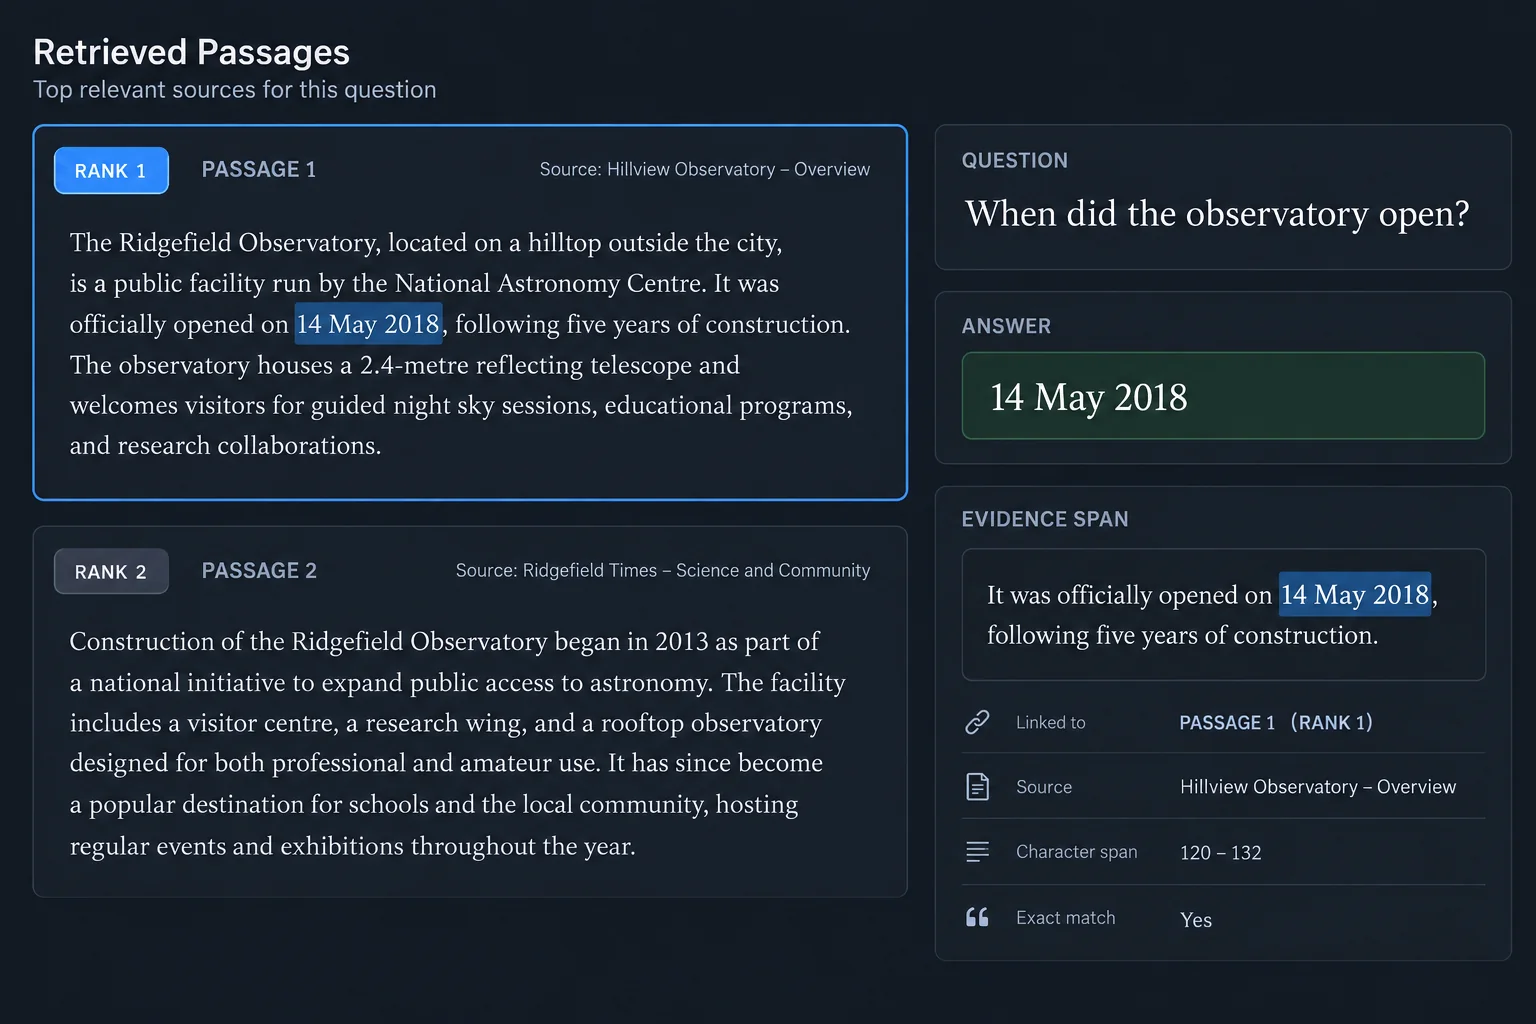
Question Answering (QA) & Passage Retrieval Ground Truth

SQuAD-style span-extractive, multi-hop, and generative question-answer pair authoring tied to specific source passages to train retrieval-augmented generation (RAG) and machine reading comprehension models.

Natural Language Inference (NLI) & Semantic Similarity

Pairwise sentence labeling categorizing semantic relationships into Entailment, Contradiction, or Neutral states, alongside graded Semantic Textual Similarity (STS) scoring for cross-encoders and embedding models.

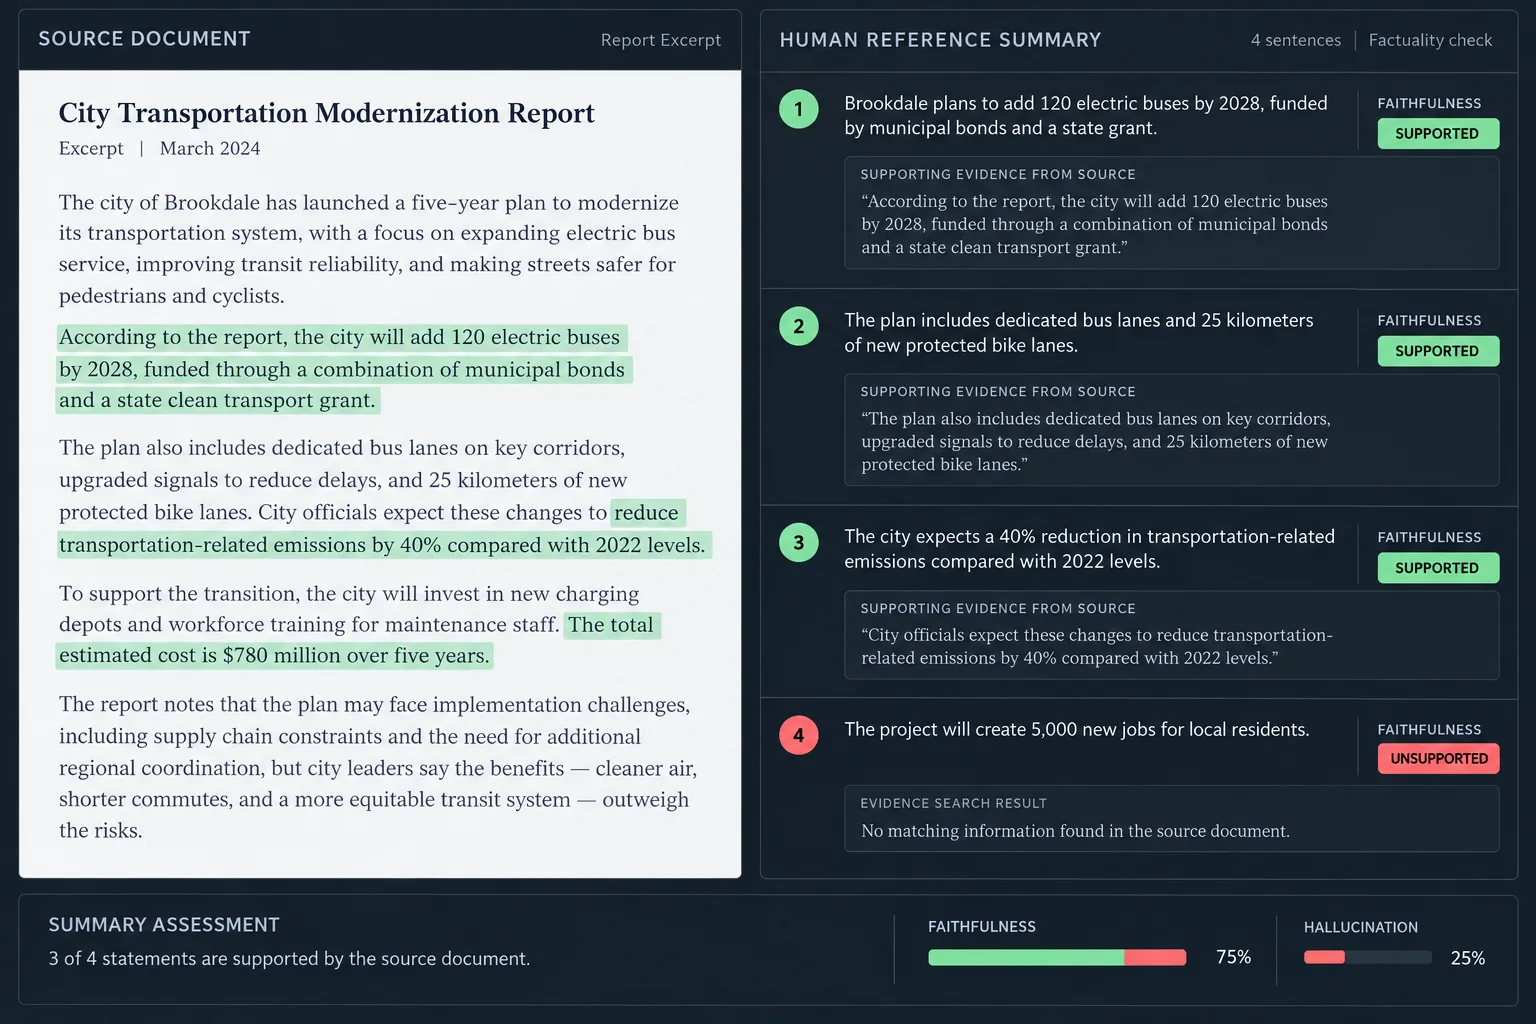
Text Summarization & Hallucination Verification

Generation of human reference summaries (extractive and abstractive) paired with sentence-level faithfulness labeling, factual consistency verification, and hallucination detection against source documents.

Trust & Safety Content Moderation

Rigorous multi-label categorization tagging policy violations—including hate speech, harassment, profanity, violent extremism, self-harm cues, and brand-safety risks—against strict platform guidelines.

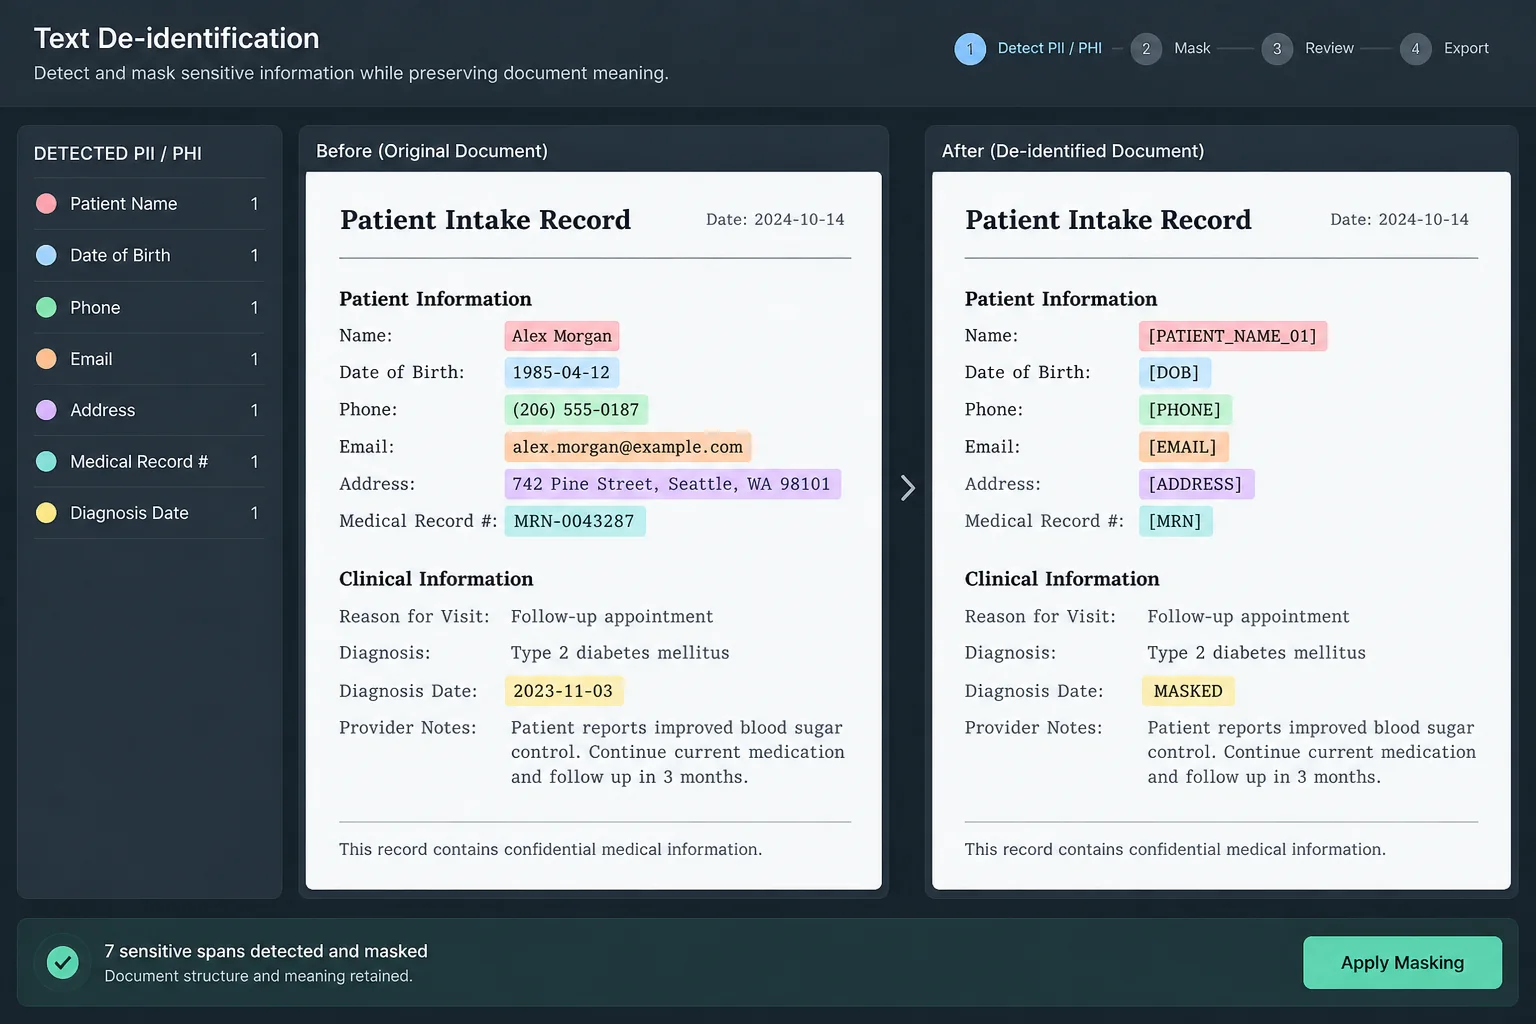
Text De-Identification & PII Masking

Span-accurate detection and replacement (redaction, hashing, or synthetic surrogate swapping) of Personally Identifiable Information (PII) and Protected Health Information (PHI) to ensure regulatory compliance prior to model training.

Clinical & Biomedical NLP Annotation

Specialized medical record annotation executed by qualified clinicians, mapping unstructured clinical notes, pathology reports, and discharge summaries to standardized ontologies (UMLS, ICD-10, SNOMED-CT, RxNorm).

Legal Contract & Clause Extraction

Paralegal-vetted identification, classification, and extraction of standard and non-standard clauses—including indemnification, governing law, termination triggers, and confidentiality terms—across corporate agreements and regulatory filings.
FLEXIBLE DELIVERY

Tooling & Platform-Agnostic Execution

01

Client-Hosted Platforms

Our language annotation teams can work directly inside client-approved text-labeling environments supporting span annotation, entities, classification, relationships, attributes, and review workflows, including Label Studio, SuperAnnotate, Kili Technology, or other approved systems.

LABEL STUDIOSUPERANNOTATEKILICLIENT HOSTED
02

Proprietary Client Consoles

Annotators can operate within client-owned NLP platforms through approved secure access, following your existing taxonomy, span rules, keyboard workflow, relation schema, language conventions, and review stages.

CLIENT UIVPNPOD
03

Josisoft Managed Infrastructure

When no production annotation platform is available, we can configure controlled project workspaces around your text corpus, label taxonomy, entity definitions, relation schema, role permissions, and QA stages.

CONTROLLEDCONFIGUREDMANAGED
DEPLOYED CONTEXT

Real-World Text & NLP Applications

Conversational AI & Support Data

Annotate intents, entities, requests, topics, actions, and structured language signals across chat, support, assistant, and customer-service datasets.

Search, Ecommerce & Catalog Intelligence

Label product attributes, queries, categories, named entities, relevance signals, and semantic relationships across search and ecommerce text datasets.

Enterprise Documents & Knowledge Data

Annotate entities, sections, concepts, relationships, and domain terminology across reports, records, internal documents, knowledge bases, and operational content.

Multilingual NLP Datasets

Create structured text annotations across languages, scripts, regional variations, transliteration requirements, and client-defined multilingual taxonomies.

CONTROLLED OPERATIONS

Security, Compliance & Workforce Governance

01

Mandatory Bilateral NDAs

Every annotator, QA reviewer, and project manager signs an NDA before accessing project assets.

02

Security & Clean-Room Training

Personnel are trained on data confidentiality: strict restrictions on screen sharing, zero tolerance for screen recording or screenshots, and supervised session management.

03

Governed Physical Delivery Hub

On-premise operations at our central Durgapur facility enforce controlled local networks, restricted USB and removable media ports, and supervised work environments.

04

Isolated Hybrid Pods

Each client is assigned a dedicated team working in siloed environments, preventing cross-project data contamination and maintaining domain context.

START A PROJECT

Start With a Calibrated NLP Annotation Pilot.

Share a representative text sample, label taxonomy, annotation guidelines, language requirements, and QA criteria with our delivery team. We will calibrate the schema, annotate a controlled pilot batch, review ambiguous language and edge cases, and return the sample for acceptance before production scaling.

Request a Pilot Batch