Our Mission
To deliver governed, high-precision training data and language services that accelerate production AI, while providing ethical, sustainable employment and continuous digital upskilling across our diverse workforce.
For over ten years, Josisoft Technologies engineered enterprise web platforms, mobile applications, and automation systems for global clients. Today, we bring that foundational software engineering rigor to AI data and language operations—serving not just as an annotation vendor, but as a trusted, long-term technical partner in your model development lifecycle.
To deliver governed, high-precision training data and language services that accelerate production AI, while providing ethical, sustainable employment and continuous digital upskilling across our diverse workforce.
To become the most trusted, transparent partner for global AI innovators—bridging complex unstructured data and verified ground truth through engineered milestone gates and human cultural intelligence.
We differentiate ourselves from black-box data shops through a disciplined delivery model built on four foundational commitments.
Structured QA protocols, gold-standard benchmark calibration, and multi-tier SME adjudication systematically eliminate annotation noise and label drift.
Mandatory NDAs across all personnel, air-gapped data handling, role-based access controls, and strict confidentiality training protect proprietary IP at rest and in transit.
Grounded in a decade of software sprint planning, our pipelines follow structured milestone gates and clear delivery stages to keep model training schedules on track.
Zero black-box handoffs. Proactive status tracking, real-time edge-case escalation logs, and direct engineer-to-engineer communication keep you informed at every phase.
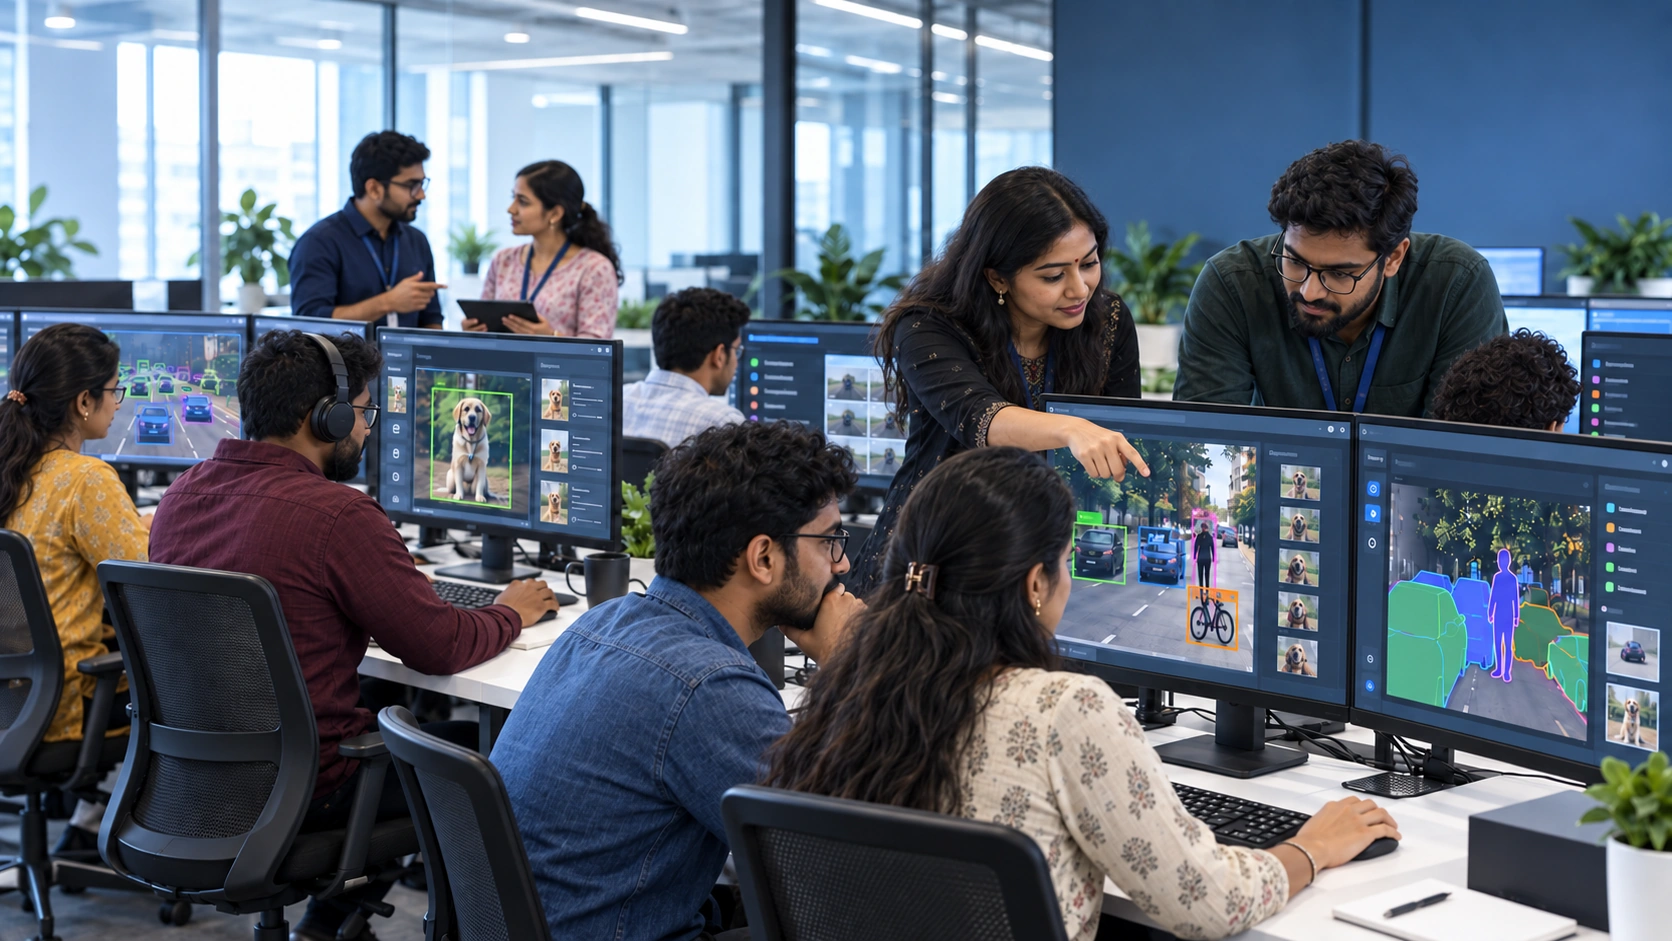
Our centralized facility houses core software engineers, project delivery directors, and quality leads. This team oversees pipeline infrastructure, manages client security compliance, enforces data governance, and monitors batch throughput velocity.
Our distributed network of domain-specialist annotators and native linguists operates remotely under strict non-disclosure agreements (NDAs). Every remote contributor completes rigorous data protection training and security clearance before receiving project tasks.
Led by seasoned software engineers and frontline data operations veterans with proven track records managing large-scale annotation projects, multi-tier QA pods, and complex labeling workflows.
Share your dataset requirements, target volume, and acceptance criteria. Our engineering team will review your specifications and structure a custom delivery plan.