
Instruction-Response Pair Creation
End-to-end authoring of single-turn instruction and target response pairs demonstrating ideal task execution, reasoning depth, tone, and conciseness for foundational model fine-tuning.
Fine-tuning data teaches a model how a high-quality response should look for a specific task, domain, or instruction style. Josisoft builds supervised fine-tuning workflows around your prompt schema, target behavior, response format, domain requirements, acceptance criteria, and QA process so each example provides a clear, consistent demonstration of the behavior you want the model to learn.
Talk to a Data Specialist“Summarize the customer issue and provide the next recommended action.”
The customer reports that a replacement device arrived, but the activation process stops after account verification. Two restart attempts did not resolve the issue.
SOURCE CONTEXT · VERIFIEDEnd-to-end authoring of single-turn instruction and target response pairs demonstrating ideal task execution, reasoning depth, tone, and conciseness for foundational model fine-tuning.

Multi-turn conversational dataset authoring designed to train chat models on contextual memory retention, persona consistency, clarification behaviors, and natural back-and-forth dialogue flows.
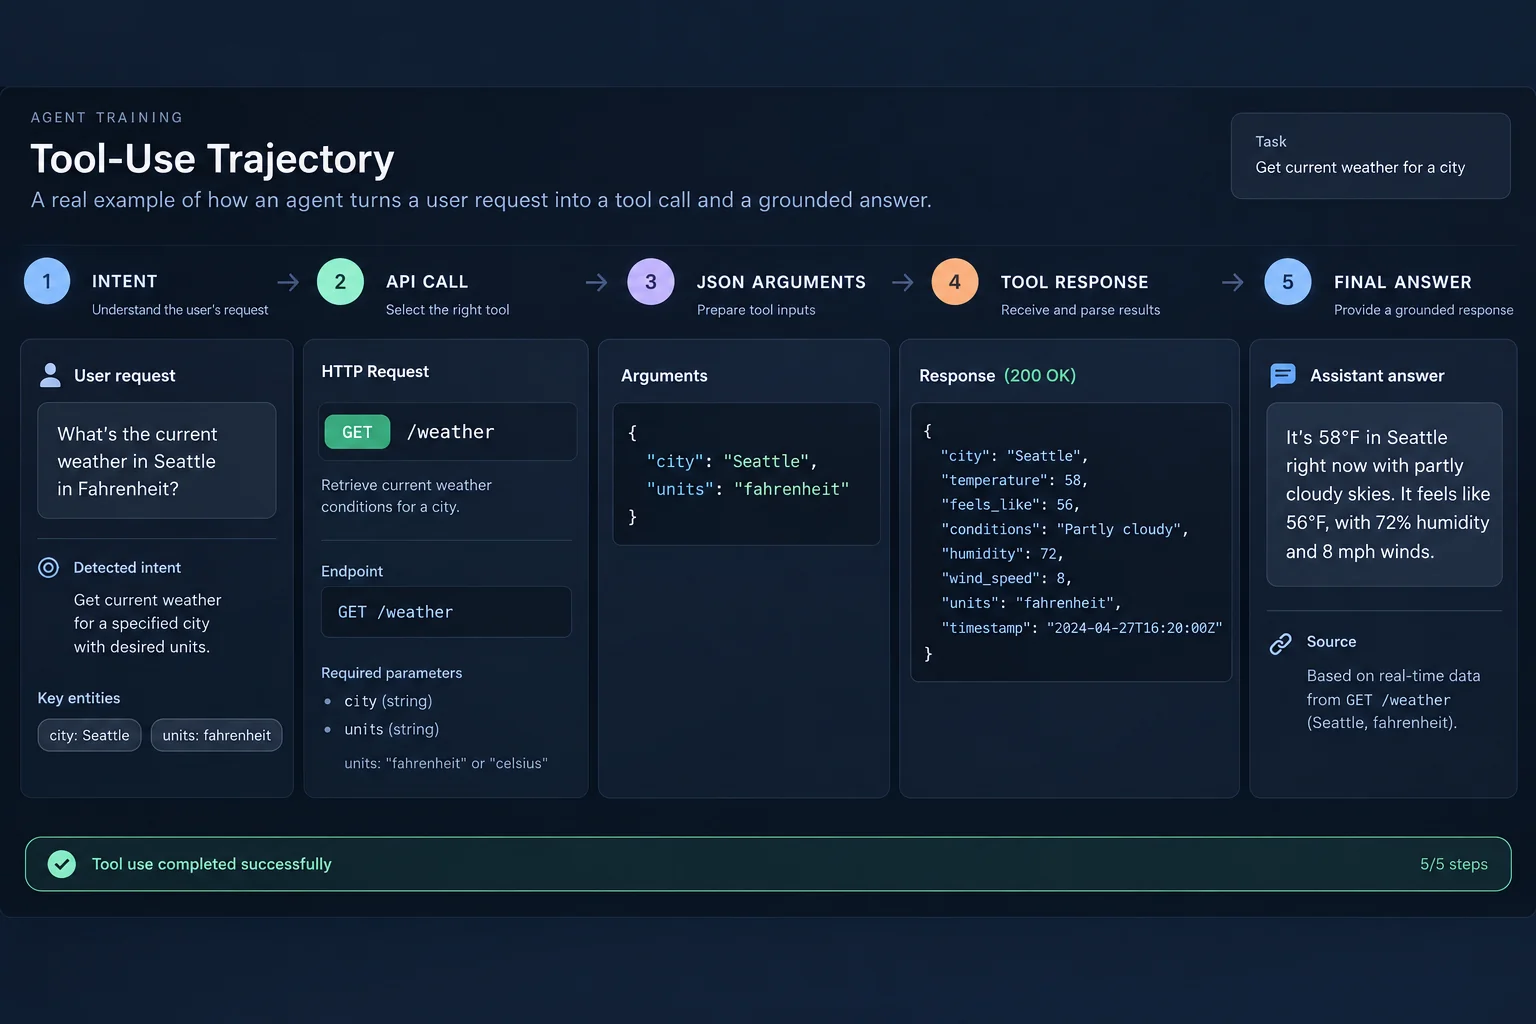
Multi-step training demonstrations teaching models how to identify intent, formulate valid API calls and JSON arguments, and parse execution responses to accomplish complex tasks.
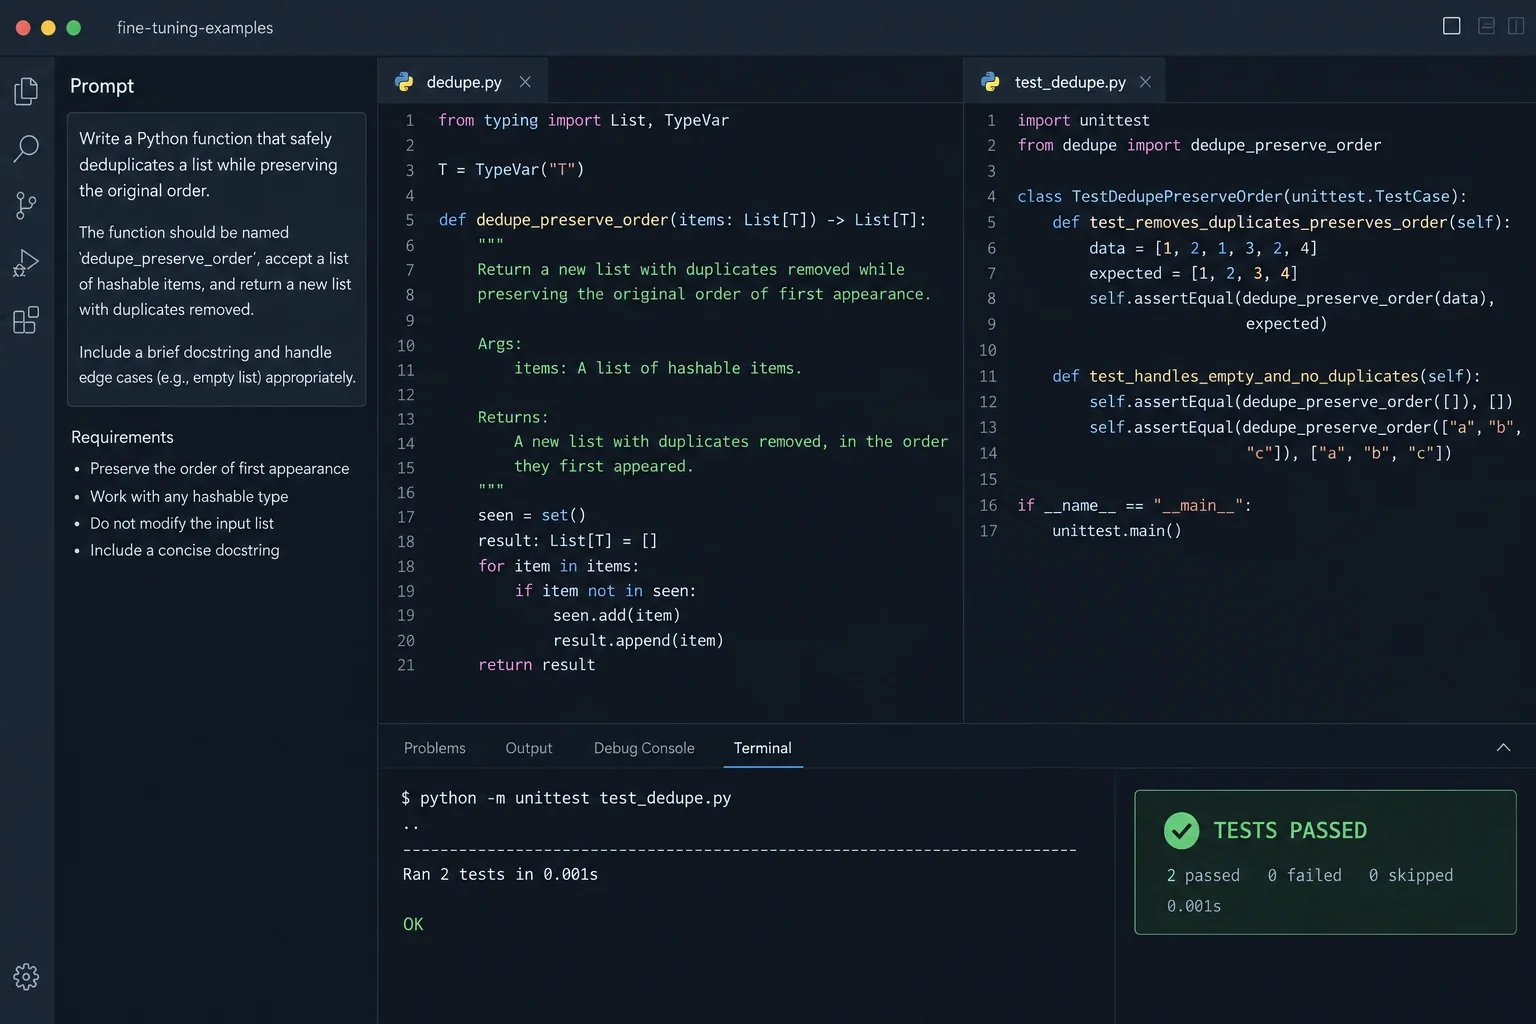
High-precision programming demonstrations covering end-to-end software development, unit test creation, code translation, debugging, and SQL generation authored by vetted software engineers.

High-complexity training pairs authored and validated by credentialed subject-matter experts across medicine, law, finance, and engineering for enterprise vertical models.
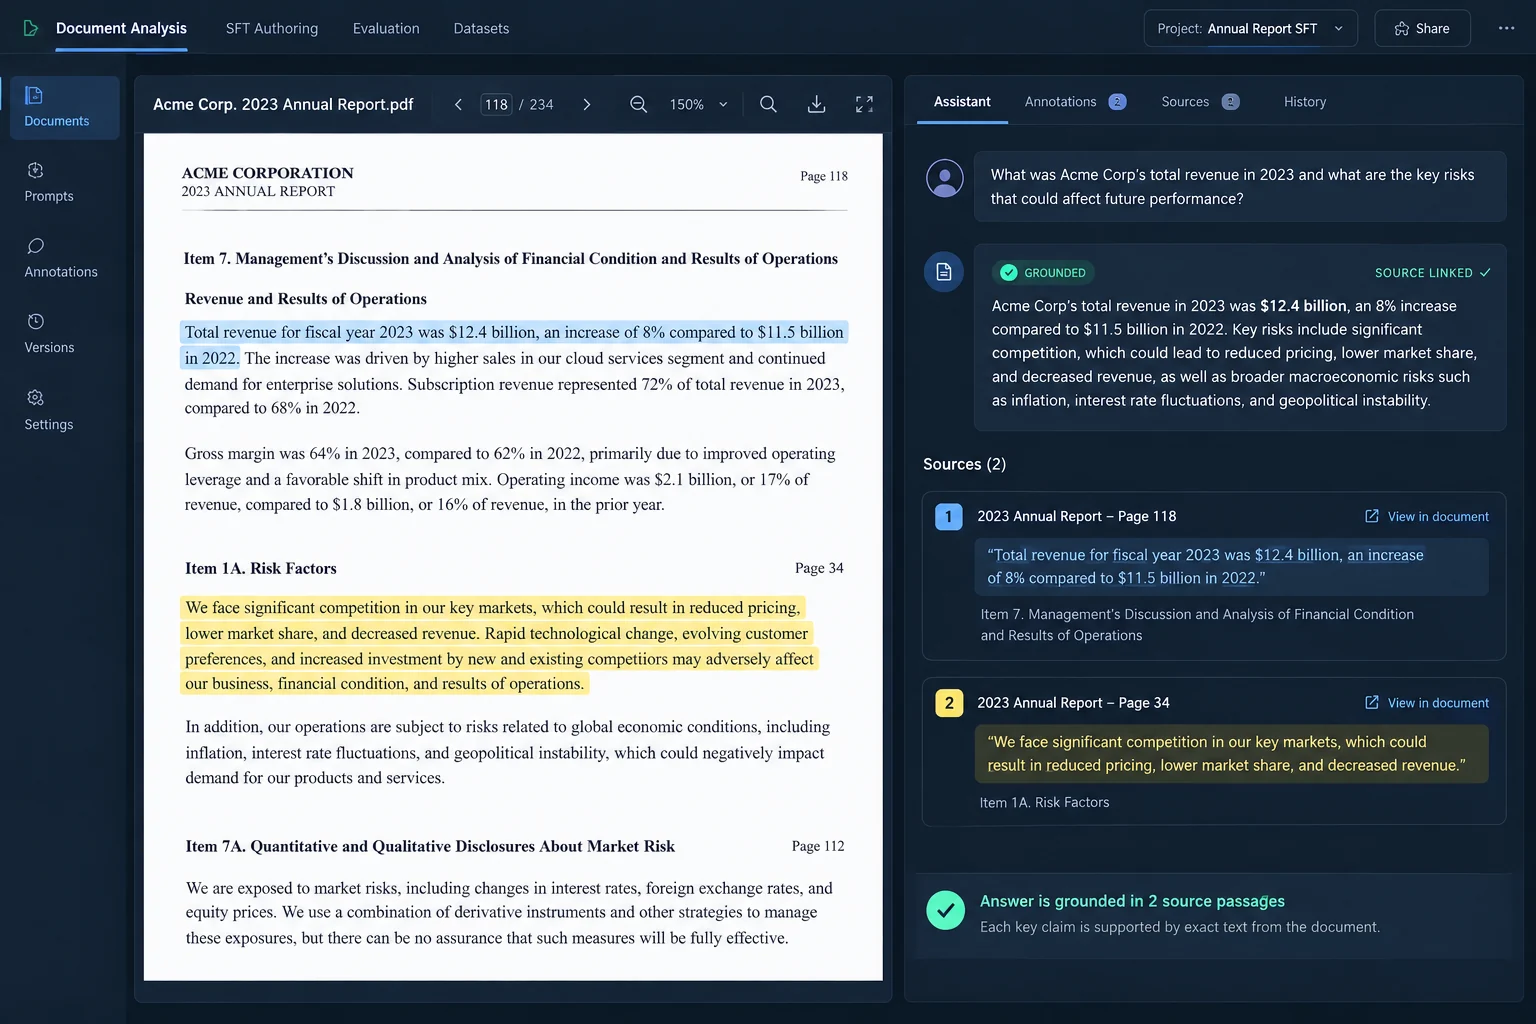
Instruction pairs built over long-form reference materials—including financial filings, technical manuals, and legal briefs—teaching models factual extraction, synthesis, and grounded reasoning without hallucination.

Human-in-the-loop editing and upgrading of weak, incomplete, or synthetic model drafts into publishable, gold-standard reference demonstrations.
Our teams can work directly inside client-approved environments supporting instruction-response creation, editing, structured fields, reviewer feedback, task routing, and QA workflows.
Contributors and reviewers can operate within client-owned fine-tuning data systems through approved secure access, following your task templates, response schema, style guide, domain instructions, quality checks, and review stages.
When no production environment is available, we can configure controlled project workspaces around your prompt sets, target behaviors, response templates, contributor roles, reviewer roles, and QA/adjudication stages.
Rewrite for clarity.
Clear · concise · complete
Create instruction-following demonstrations for summarization, rewriting, extraction, explanation, transformation, classification, and other general language tasks.
Build curated examples using domain terminology, workflows, context, and structured outputs for enterprise or specialized assistant use cases.
After account verification
Create demonstrations for issue summarization, response drafting, next-action recommendations, ticket classification, troubleshooting, and structured service workflows.
{"action":"validate",
 "target":"account",
"priority":"standard"}Create training examples where models must produce structured outputs, follow schemas, select actions, format data, or generate consistent machine-readable responses.
Every annotator, QA reviewer, and project manager signs an NDA before accessing project assets.
Personnel are trained on data confidentiality: strict restrictions on screen sharing, zero tolerance for screen recording or screenshots, and supervised session management.
On-premise operations at our central Durgapur facility enforce controlled local networks, restricted USB and removable media ports, and supervised work environments.
Each client is assigned a dedicated team working in siloed environments, preventing cross-project data contamination and maintaining domain context.
Share a representative task set, prompt format, target response behavior, output schema, style requirements, and QA criteria with our delivery team. We will calibrate contributor guidelines, create a controlled pilot batch, review difficult examples and consistency issues, and return the sample for acceptance before production scaling.